XGenAct: Geometry-Enhanced World Action Models through Cross-Task Generation
Published in arXiv preprint arXiv:2610.03516, 2026
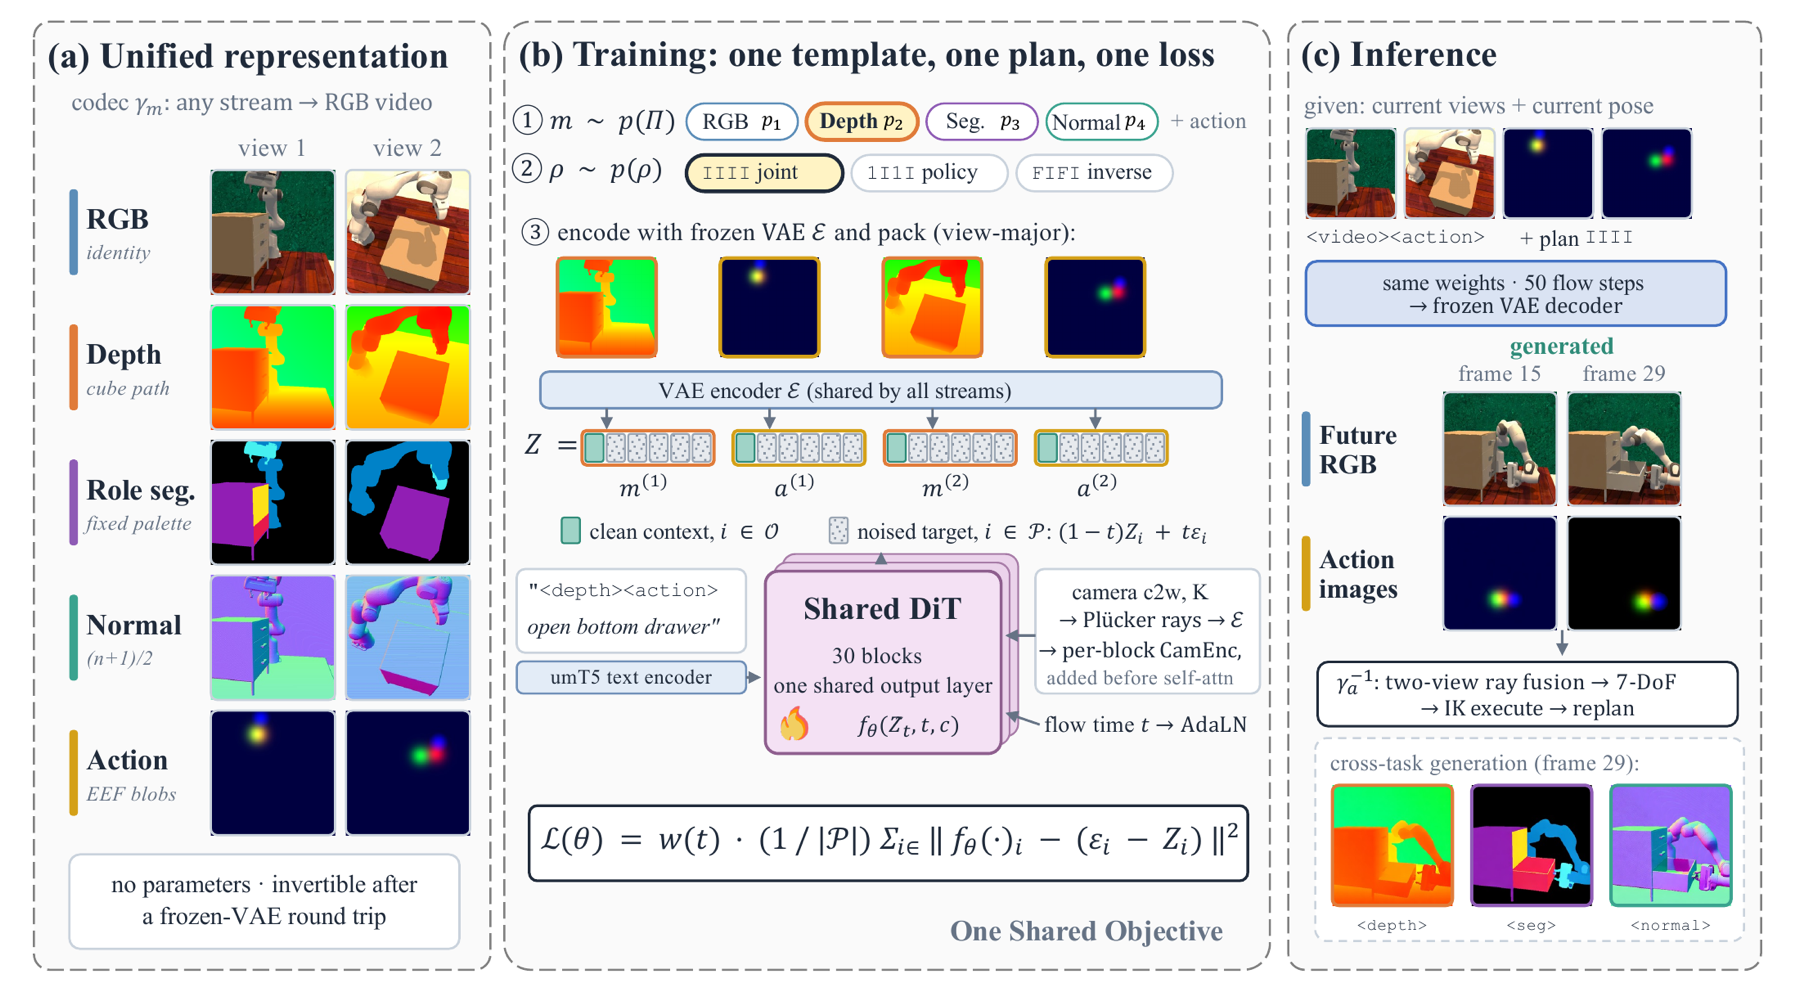
World action models (WAMs) predict how observations and actions evolve over time, but RGB-and-action future prediction does not explicitly capture the spatial structure needed for manipulation. XGenAct represents RGB observations, robot actions, metric depth, surface normals, and functional role segmentation as RGB videos through deterministic codecs. By sampling perception and action tasks during training, it uses one video diffusion transformer and one objective to learn temporal prediction across these spaces, without modality-specific learned heads.
On held-out RLBench tasks, structured perception training improves average closed-loop success over RGB-only training. XGenAct reaches 52% success in the five-task external comparison, versus 26% for the strongest evaluated baselines, and predicts future depth and segmentation more accurately than pipelines that generate RGB first and then apply a frozen perception expert.